
Unlimited OCR 2: developer tools for developers and technical teams
Official site link, not an affiliate link. We do not have an approved referral link for Unlimited OCR 2.
Unlimited OCR 2 helps you make documents and slides by this route: baidu’s free, MIT-licensed model that turns very long documents into text in one run. It is best for developers and technical teams who need to turn long PDFs, reports or scanned books into text and tables. People also use it to build software. A free plan is available.
What it does
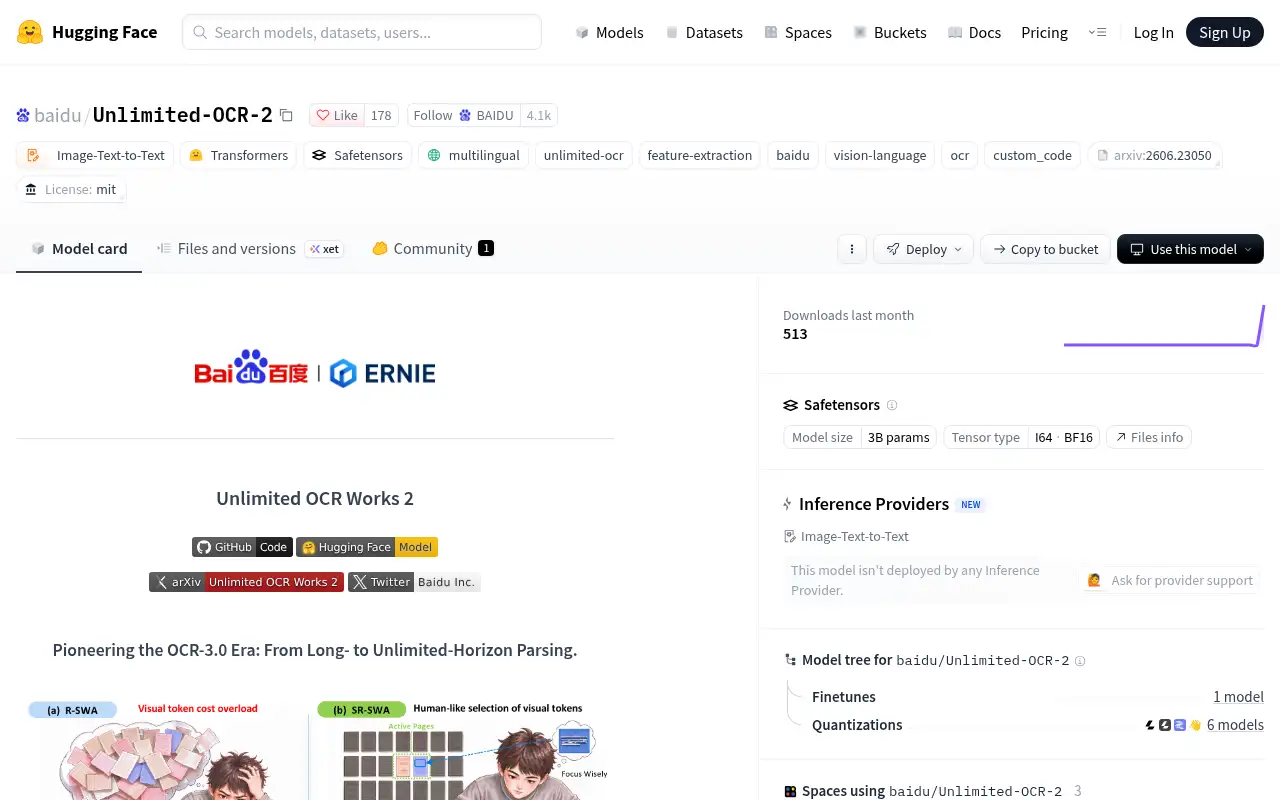
Most OCR models handle a page or a short document at a time. Baidu says Unlimited OCR 2 uses a new attention method, Sparse Reference Sliding Window Attention, that keeps only a fixed set of working references, so it can keep reading without its memory use growing with the document. The model is about 3.3 billion parameters on Hugging Face. Baidu also released MarathonDocBench, a benchmark for very long document parsing, and the model is on ModelScope and Baidu Cloud, per its model card.
Official site:huggingface.co/baidu/Unlimited-OCR-2.
Editorial note
Baidu released Unlimited OCR 2 on October 27, 2026. It is an open, MIT-licensed vision-language model that Baidu says can parse documents of unlimited length in a single run, keeping per-step memory and speed nearly constant however long the document is.
Who it’s for
- For: Developers and technical teams who need to turn long PDFs, reports or scanned books into text and tables.
- Not ideal for: non-technical users who want a ready-made app; this is a model you set up and run yourself.
Key use cases
- Slides & docs
- Build apps & code
What you can do with it
- Free access: Baidu publishes Unlimited OCR 2 on Hugging Face under the MIT license, so the model weights are free to download and use. You run it on your own hardware, and there is a free web demo on Hugging Face Spaces. This matters when you want to test before you pay.
- Web demo plan: Try it in the browser on Hugging Face Spaces. This matters when the free tier is not enough.
- Help documentation: Official pricing and product pages at huggingface.co/baidu/Unlimited-OCR-2. This matters when you set it up yourself.
How to use Unlimited OCR 2: step-by-step tutorial
Five to eight steps from the account to a first useful result. Where the official guide names a control, the step uses that name. Where it does not, the step stays general.
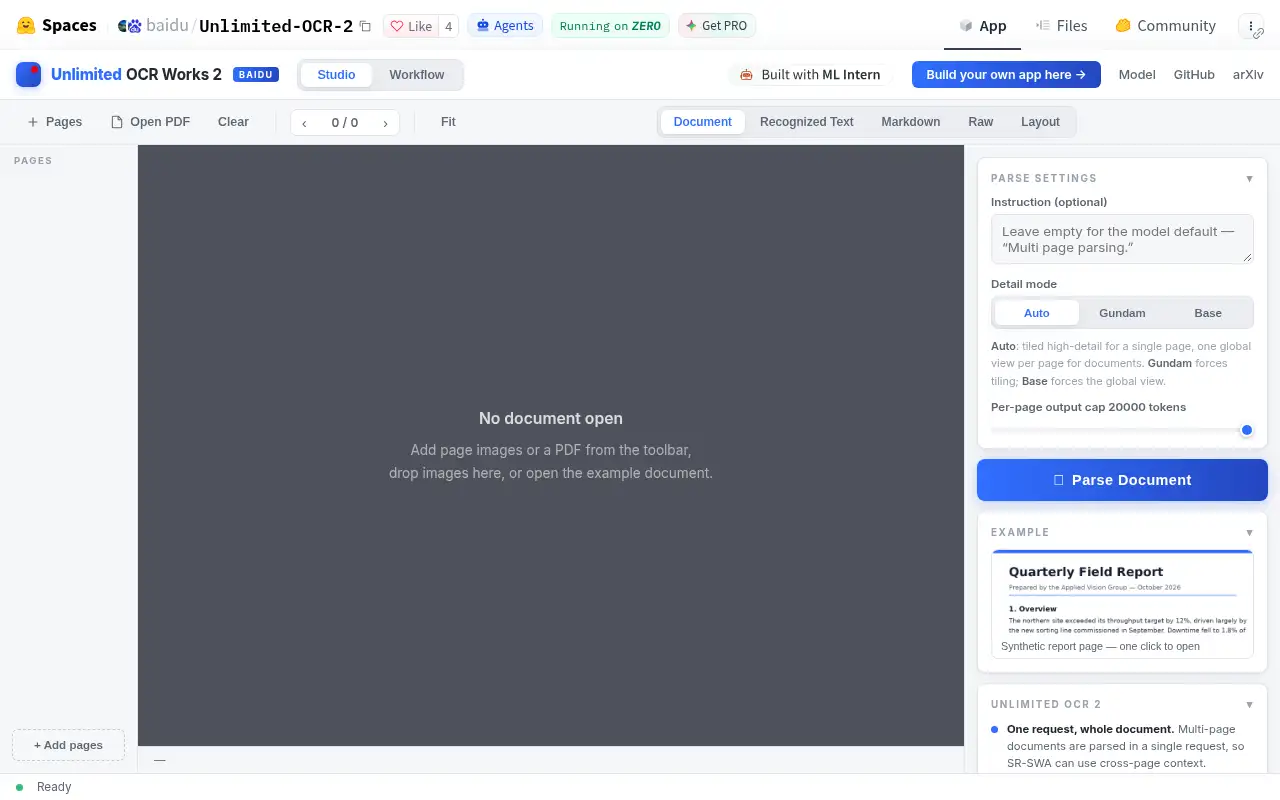
- Open the free Unlimited OCR 2 demo on Hugging Face Spaces and upload a sample document.
- Check that tables and reading order come out the way you need.
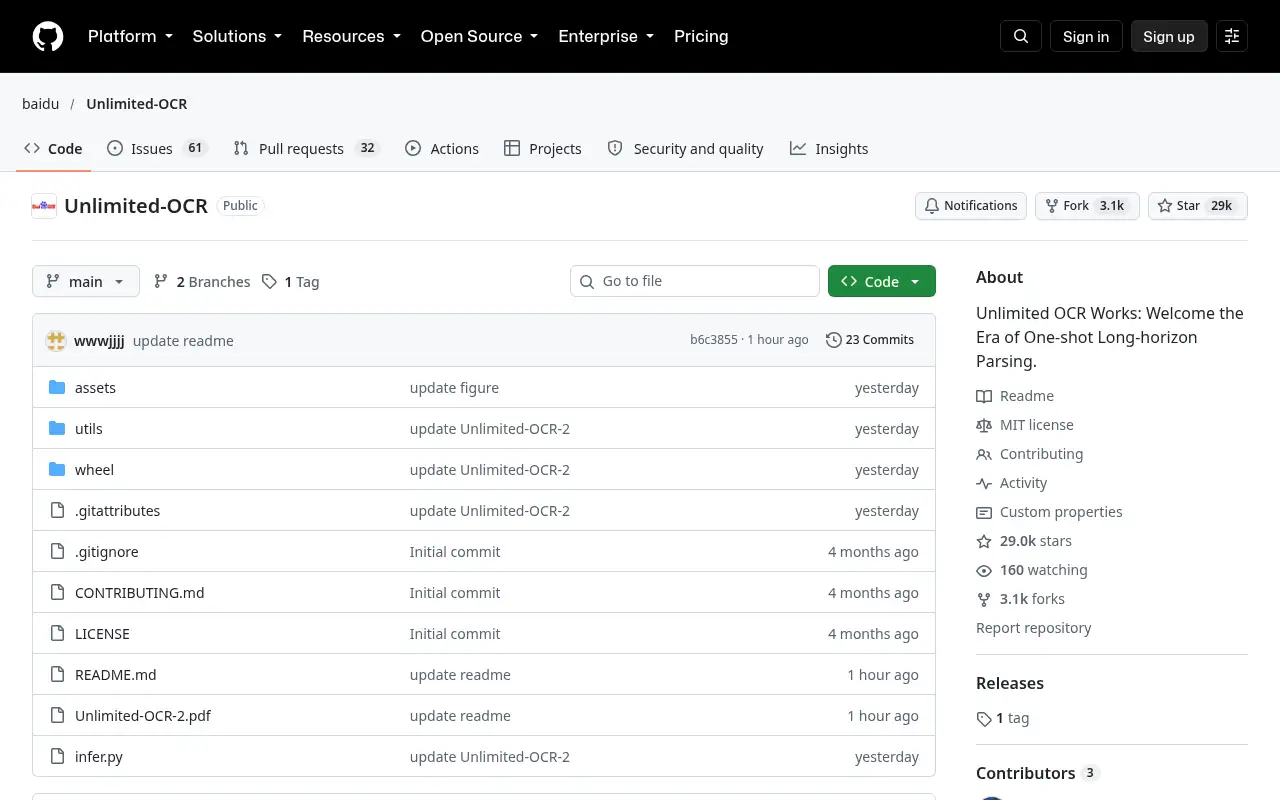
- For real use, follow the setup on the Hugging Face model card or the GitHub repo.
- Run it on a machine with a GPU, using Transformers or vLLM.
- Spot-check the text against the original before you rely on it.
These steps follow the official guide: Unlimited OCR 2 model card (Hugging Face).
Frequently asked questions
What is Unlimited OCR 2?
An open OCR model from Baidu, released October 27, 2026, built to turn very long documents into text in a single run, per its model card.
Is Unlimited OCR 2 free?
Yes. It is published under the MIT license on Hugging Face, checked October 27, 2026. You pay only for the hardware you run it on.
Do I need a GPU?
For practical speed, yes. It is a model of about 3.3 billion parameters that you run yourself. The Hugging Face demo lets you try it without one.
What makes it different?
Baidu says its Sparse Reference Sliding Window Attention keeps decoding speed and memory nearly constant regardless of document length.
Where can I get it?
On Hugging Face (baidu/Unlimited-OCR-2), with code on GitHub (baidu/Unlimited-OCR), and on ModelScope and Baidu Cloud, per Baidu.
Pricing
Prices checked on the official pricing page.
- Open model (MIT)
-
Free
Download the weights from Hugging Face and run them yourself with Transformers or vLLM
- Web demo
-
Free
Try it in the browser on Hugging Face Spaces
- Limits: Accuracy claims are Baidu’s own; you need your own hardware for real workloads, and results should be checked on your documents.
- Plans change: vendors update limits and prices; confirm on the official page before you buy.
Facts
- Access
- Ongoing free plan
- Paid plans from
- Free
- Checked
- Category
- Category: Development tools (31 in the library).
- On the record
- Baidu publishes Unlimited OCR 2 on Hugging Face under the MIT license, so the model weights are free to download and use. You run it on your own hardware, and there is a free web demo on Hugging Face Spaces.